
University of Zambia students classify Labour Force Survey responses by occupation and industry, creating a ground truth dataset to evaluate ZEL’s AI-assisted classification tool.
How Zambia is improving AI evaluation with ground truth data
How can governments know whether AI systems are performing accurately? As AI is increasingly deployed in high-stakes, data-scarce settings, reliable ground truth data is essential for evaluating performance. Drawing on the Zambia Evidence Lab's work classifying labour force survey data, this blog explores how to build trustworthy datasets for AI evaluation in low- and middle-income countries.
AI applications are increasingly deployed in high-stakes, data-scarce contexts. Without reliable ground truth data, it is difficult to know whether these applications are actually performing well. Drawing on the Zambia Evidence Lab’s AI-assisted classification of Zambia’s labour force data, this blog explores what it takes to build trustworthy datasets for evaluating AI.
AI needs reliable ground truth data
Public attention often focuses on which AI models are most capable. Far less attention is paid to ground truth data, the trusted labels or values used to evaluate AI systems. This is worrying because AI is increasingly applied in high-stakes domains such as health, agriculture and finance.
If the ground truth is unreliable, performance estimates can give false confidence in systems used for important decisions. This risk is heightened in low- and middle-income countries (LMICs), where high-quality, representative ground truth data is often scarce.
Building ground truth data often involves assigning labels to text, images or recordings, where the ‘correct’ label is not always obvious. ZEL explored this challenge while developing an AI-assisted tool to classify occupations and industries in Zambia’s Labour Force Survey (LFS).
Zambia’s LFS collects free-text employment descriptions, which ZEL’s pipeline classifies into internationally recognised four-digit occupation and industry codes. To evaluate AI performance, ZEL needed reliable ground truth data showing correct classifications of occupations and industries.
The experience highlighted four questions that should guide the collection of reliable ground truth data: (i) Who decides the ground truth? (ii) How is disagreement resolved? (iii) Will it generalise to real-world use? (iv) How is ground truth updated?
Who decides the ground truth? The importance of local context and domain experts
Ground truth is often shaped by human judgment. Whether someone interprets a facial expression as angry or sad depends on their lived experience. Ignoring who produces ground truth can embed distant or poorly informed judgments into a dataset.
To ensure that local context informed the LFS ground truth, ZEL first trained University of Zambia students to independently classify responses. Their familiarity with Zambia's labour market was critical to producing reliable labels.
Survey response: “She brews Kachasu beer at home and sells it.” ❌ Annotator without local context Assigns industry code 1103 - Manufacture of malt liquors and malt. The word beer is interpreted literally. ✅ University of Zambia student with local context Assigns industry code 1101 - Distilling, rectifying and blending of spirits. Identifies Kachasu as a traditional spirit produced by distillation. |
For difficult cases where students were uncertain, final labels were assigned by expert adjudicators from the Zambia Statistics Agency (ZamStats), which administers the LFS. Their experience applying international occupation and industry classifications helped resolve misleading descriptions.
Survey response: “He’s a fishmonger selling kapenta from a market stall.” ❌ Non-expert adjudicator Assigns occupation code 7511 - Butchers, Fishmongers and Related Food Preparers. The word fishmonger is taken literally, so the worker is classified as primarily preparing or processing fish. ✅ LFS expert adjudicator Assigns occupation code 5211 - Stall and Market Salespersons. Recognises kapenta, a small fish, typically sold from market stalls with limited preparation. The product is fish, but the primary activity is sales. |
These examples demonstrate why ground truth should be determined locally, because what counts as correct often depends on local language, knowledge and context. Too often, local domain experts are limited to symbolic consultation or only consulted after an AI application performs poorly.
How is disagreement resolved?
When annotators disagree, the default response is majority voting. The label selected most often becomes the truth, and confidence is placed in the annotators' 'collective intelligence'. This is practical because model evaluation often necessitates one correct answer.
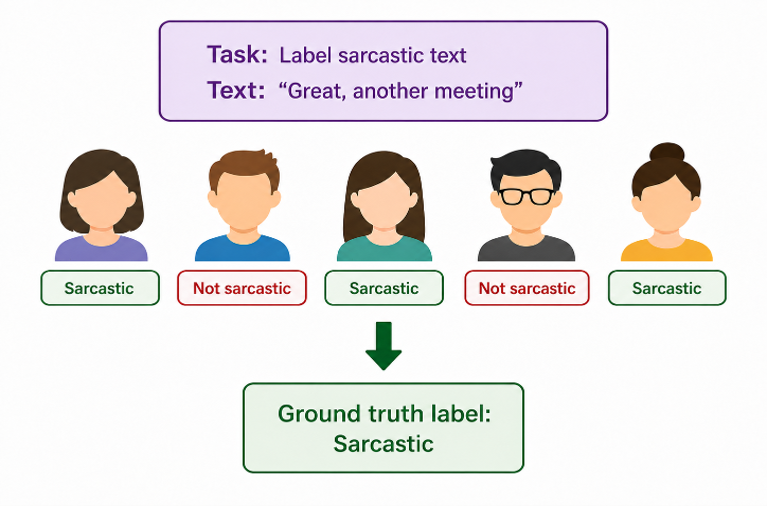
The process used to create ground truth labels shows how multiple annotators review data and disagreements are resolved through majority voting.
Perspectivist approaches challenge this method. They treat disagreement as evidence that a case may be ambiguous, information may be missing, or several interpretations may be defensible.
Even seemingly objective labelling tasks can produce substantial disagreement. In one study of sleep-stage classification, three experts disagreed on 44% of 10,349 cases, and 37% of disputed cases remained unresolved after three rounds of collective adjudication.
ZEL’s LFS data presents a similar problem. A vague description may support several plausible occupation or industry codes because the information needed to distinguish between them was never recorded. ZEL still needs one adjudicated label to benchmark the model performance, but selecting one code does not remove the underlying ambiguity.
A stronger ground truth would therefore retain two layers: the final adjudicated code used to calculate accuracy, and the full set of annotator classifications, agreement levels and reasons for difficult decisions. This creates a usable benchmark, while recognising that the majority label may not be the only defensible answer.
Will AI systems generalise to real-world use?
Performance on clean or artificial examples says little about how an AI system will behave once deployed. In India, eye-disease detection models that performed well on pristine images struggled when small specks of dust appeared in real-world scans. Ground truth must therefore reflect the task as it appears in practice.
For the LFS ground truth, ZEL used historical survey records. This meant the AI was evaluated on the same free-text descriptions recorded by enumerators, including vague wording, spelling variation and local terminology. This also exposed limits in the survey data itself. If an enumerator records only a vague description such as “farmer” or “businesswoman”, neither an expert annotator nor an AI model can recover the missing detail needed to assign a precise four-digit code.

Comparing AI model performance using different versions of the ground truth dataset reveals how updates to labelled data affect evaluation results.
In response, ZEL and ZamStats are piloting stronger enumerator training, clearer probing guidance and changes to LFS questions so that more detailed occupation and industry descriptions are recorded in the field.
How is ground truth data updated?
Ground truth is not static. A model may perform well today, but its accuracy can weaken as the real world around it changes. New behaviours, terminology, or data collection practices can all affect whether past performance still holds.
The LFS pipeline shows why regular review matters. AI-assisted classification improved accuracy by up to 17 percentage points, reduced classification costs to around US$10 for an annual LFS sample, and cut processing time from roughly 1,000 hours to 30 minutes. These gains create an opportunity to use human expertise differently.
Instead of spending time manually classifying every survey response, ZamStats experts can review a targeted sample of AI classifications each year. This helps check whether AI performance still holds as Zambia’s labour market changes, new occupations emerge, or recorded descriptions change.
These reviews update the ground truth, help to refine the AI-classification pipeline and show where survey questions or recording practices need to improve. Reliable ground truth is therefore not a one-off dataset. It is part of an ongoing review process that keeps the AI system relevant as conditions change.
Key recommendations for improving AI evaluation
- Invest in ground truth: Governments, funders and AI developers should support open datasets, annotation tools and incentives that reward careful, context-specific data work, especially in low- and middle-income countries.
- Give local domain experts authority: Local experts should help define categories, design annotation guidance and have sustained participation in resolving difficult cases.
- Interrogate data collection: Before labelling data, ask whether the original collection process captures the right information and reflects real-world conditions.
- Preserve disagreement: Majority voting may provide a practical reference label, but projects should also retain annotator responses, confidence and reasoning so that ambiguity and alternative interpretations remain visible.
- Make ground truth dynamic: Ground truth should be reviewed, updated and used to audit model performance over time, so that AI systems keep pace with real-world developments.